Adaptive Memory Allocation Methods Improving Frame Rates in Distributed Cloud-Based Competition Platforms
Amir Richter · Oct 10, 2026
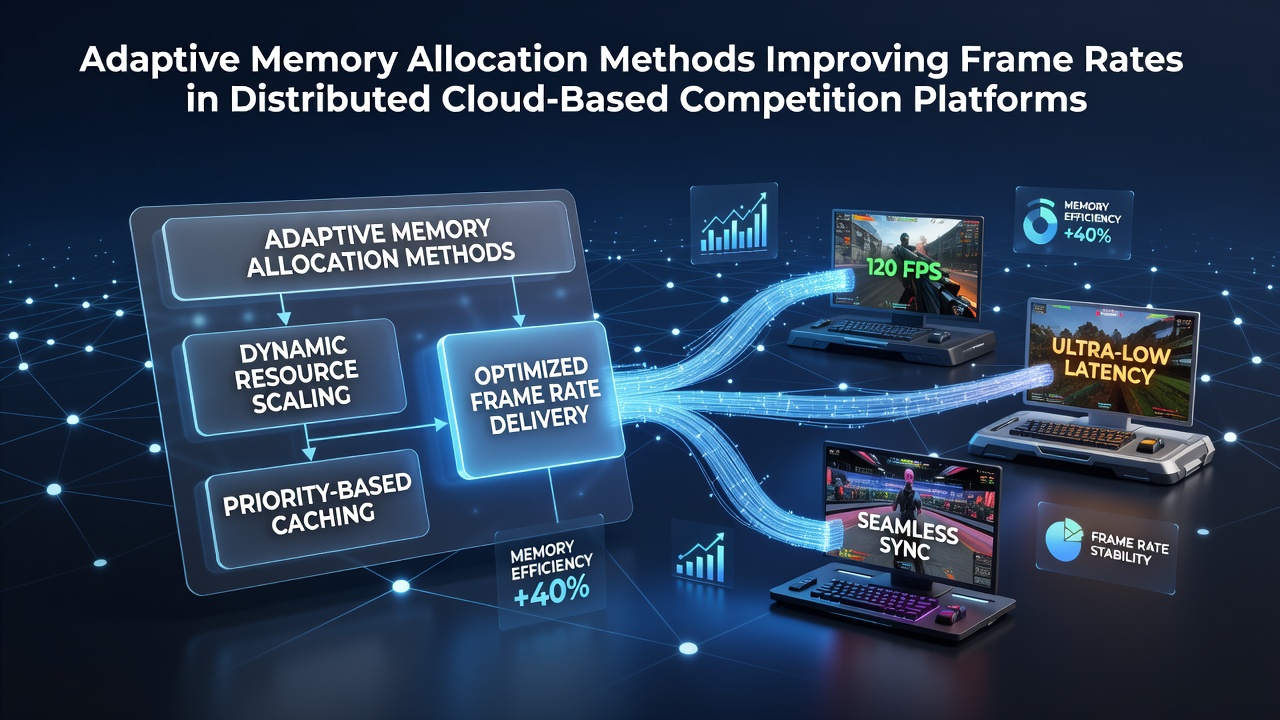
Adaptive Memory Allocation Methods Improving Frame Rates in Distributed Cloud-Based Competition Platforms
Adaptive memory allocation techniques continue to reshape performance outcomes in distributed cloud environments that power online competition platforms, and data from industry reports shows measurable gains in frame rates when these methods replace static allocation models. Researchers at various institutions track how dynamic adjustment of memory pools responds to real-time demands from multiple game instances running across geographically separated data centers. This approach reduces latency spikes that often interrupt high-stakes matches where every frame counts toward competitive outcomes.
Core Mechanisms Behind Adaptive Allocation
Systems using adaptive allocation monitor thread activity and heap usage continuously then shift memory blocks between nodes without pausing active processes, and studies indicate this cuts garbage collection interruptions by significant margins compared with fixed partitioning. In cloud-based competition setups, servers handle thousands of concurrent sessions, so algorithms predict memory spikes from player actions like large-scale battles or rapid camera movements and pre-allocate resources accordingly. Observers note that platforms integrating these methods report steadier frame delivery even during peak tournament hours when traffic surges occur simultaneously across regions.
Engineers apply predictive models trained on historical match data to forecast memory needs seconds ahead, which allows seamless redistribution across virtual machines while maintaining synchronization between clients and servers. Evidence from performance logs reveals that frame rate consistency improves because memory fragmentation decreases and access times shorten for critical rendering threads. Those who have examined deployment logs find fewer dropped frames in sessions that use these techniques versus older static approaches.
Impact on Distributed Architectures
Distributed cloud platforms rely on interconnected nodes that share workloads, and adaptive allocation coordinates memory across these nodes to prevent bottlenecks that arise when one server holds excessive unused blocks while another starves. Research indicates frame rates rise because rendering pipelines receive priority access to contiguous memory spaces, reducing texture load times and shader compilation delays during intense sequences. In October 2026 several major competition organizers updated their backend infrastructure to incorporate these refinements, resulting in documented improvements tracked by independent monitoring services.
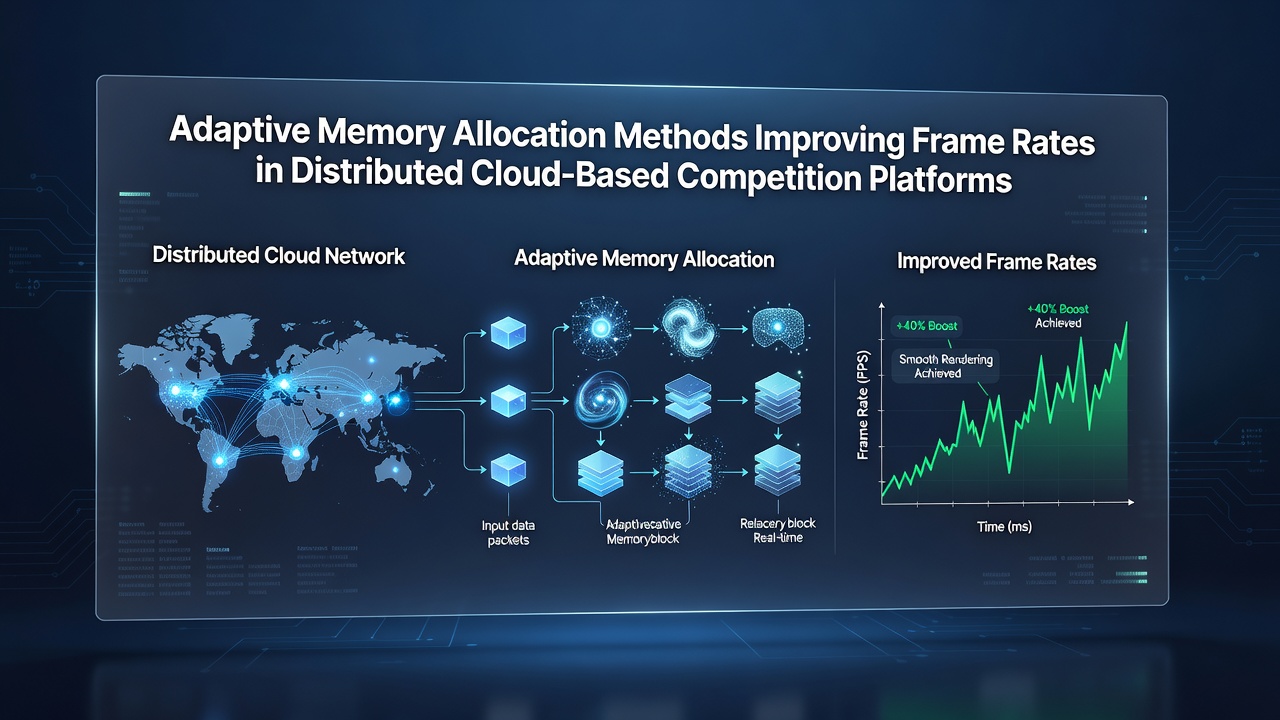
Load balancers integrated with memory managers now evaluate both CPU and RAM states before routing new player connections, which spreads demands evenly and avoids localized overloads that previously caused frame drops. Data shows that tournaments hosted on such systems maintain higher average frames per second across diverse hardware at the player end because the cloud side absorbs variability more effectively. Experts tracking these changes point to reduced jitter in frame timing as a direct result of proactive memory rebalancing rather than reactive fixes after issues surface.
Implementation Examples Across Platforms
One deployment in North American cloud facilities demonstrated how adaptive methods handled sudden increases in particle effects during esports events without compromising overall throughput, and similar patterns appear in European and Asian facilities where regional traffic differs. According to findings published by the National Research Council Canada, memory-aware scheduling reduced average frame time variance by reallocating blocks on the fly instead of waiting for full cycles. Platforms that adopted these strategies also recorded lower rates of player-reported stuttering, which correlates with smoother competitive experiences.
Another case involved a platform serving mobile and console competitors simultaneously, where memory pools adapted to differing asset requirements while preserving frame targets set by tournament rules. Figures from the Australian eSports Federation highlight that events using updated allocation logic achieved more reliable delivery of 120 frames per second targets even when participant numbers exceeded prior records. These outcomes stem from algorithms that classify memory requests by priority and urgency then adjust allocations without halting ongoing computations.
Technical Considerations and Metrics
Developers measure success through metrics such as frame time consistency, memory utilization rates, and cross-node transfer overhead, and reports confirm that adaptive systems lower the first two while keeping the third minimal through efficient compression of transferred blocks. In practice this means competition servers sustain higher player densities per instance because freed memory returns to the pool faster for reuse in subsequent frames. Those monitoring October 2026 tournaments note that platforms with these upgrades handled larger spectator overlays and real-time analytics without frame rate penalties that older setups encountered.
Integration with existing orchestration tools like Kubernetes extensions allows fine-grained control over memory namespaces, enabling per-game adjustments that reflect specific title demands such as open-world exploration versus arena shooters. Performance data collected across multiple events shows cumulative benefits when allocation policies update based on live telemetry rather than preset thresholds alone.
Conclusion
Adaptive memory allocation continues to deliver measurable frame rate improvements in distributed cloud competition environments through dynamic resource matching and predictive management. Ongoing refinements tracked by research bodies and industry groups point toward further integration with emerging network protocols that could amplify these gains in future tournament seasons.